Best Practices for Data Processing🔗
Below are steps that should be followed in order to ensure your processing efforts go as smoothly as possible.
Processing Workflow🔗
-
Determine where your data is and if you need to transfer it to a new location.
-
Once your data is on the MSI, determine if has been (properly) converted to BIDS.
- Even if the person that provided the data to you says it has been successfully converted to BIDS, you should run CuBIDS on the dataset.
- If you're starting with DICOMs, see here for BIDS conversion tips.
- If you have NIfTI files that are not BIDS-compliant, you will more than likely have to write a script to finish the conversion.
-
Create a working directory in the project folder for the share you intend to work on. This is where you will put your job wrappers, logs, and status updates. Make sure to name the folder intelligently based on the study and codebase you are running.
- Make sure to check the
groupquotato ensure there's room for your process using this command:groupquota -g share_name - Do not put ABCD information of any kind on
faird.
- Make sure to check the
-
Copy the respective SLURM wrapper into your working directory and make adjustments for your data location and codebase.
- As you make your edits, you will need to test that it works. Instructions on modifying the script and testing are here.
- Note: it is possible that a wrapper does not exist for your codebase already, and you will have to adapt a current one to fit your needs.
-
Estimate the space and resources needed for your outputs by running the codebase you intend to run on all subjects on a small sample (3-5 subjects) first.
- For more information, see Data Storage/Tracking and Resource Optimization. Adjust the resources for your jobs accordingly.
-
Submit the rest of your jobs.
- Follow Optimizing Your SLURM Queue
-
Determine which subjects have been processed successfully.
- If you are using ABCD-BIDS, you can check the status using our audit
- You can use the error query scripts to determine which subjects ran into errors.
-
Re-run the "easy to fix" errors. These include: s3 quota errors, timeouts, and out of memory errors.
- Note: it is advisable to create a new
output_logsandrun foldereach time you submit a new batch of subjects. This will greatly improve your troubleshooting experience.
- Note: it is advisable to create a new
-
Determine which subjects have been processed successfully. (Yes, again.)
-
Rank the remaining failed subject's errors by percentage of total subjects.
- If none of the errors are greater than 10%, ask the people who want the data processed if they want you to dig into the more difficult errors. This usually depends greatly on the size of the study.
-
Create a descriptive tracking document of your subject counts.
- Successfully processed
- Failed processing categorized by why they failed
- Ideally, all the subjects left to process will be due to bad data, but that rarely actually occurs.
-
Archive your work directory.
- Sync your working directly up to an s3 bucket that you maintain with all of your working directories.
- It is recommended to sync at least the template file (or an example run script) along with a list of the successfully processed subjects and the failed subjects with why they failed.
- Someone will ask you questions later, and this will be where your answers are.
-
Add your dataset to the data tracking sheet.
Anaylsis Workflow🔗
Smoothing
- Assuming you are using XCP-D outputs for analysis, it is highly recommended to not use the smoothed outputs and instead use the unsmoothed outputs (desc-denoised for XCP-D versions 0.8.0 and up).
- It is generally best practice to wait as long as you can in the processing/analysis workflow to smooth your data. The cifti-connectivity tool (and other tools which incorporate it) facilitate this, by providing options to apply smoothing as a "step 0" when making functional connectivity matrices.
- If spatially smoothing data, a kernel size (in FWHM) equal to the voxel size is recommended as a baseline, though use cases will vary.
Tracking🔗
If you like to use basecamp to track your tasks, here is a recommendated workflow for tracking your progress using the card tables feature:
-
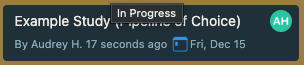
Create a basecamp data processing card for the study your processing with the codebase you are using here. We also recommend doing this for analysis and transfers.
-
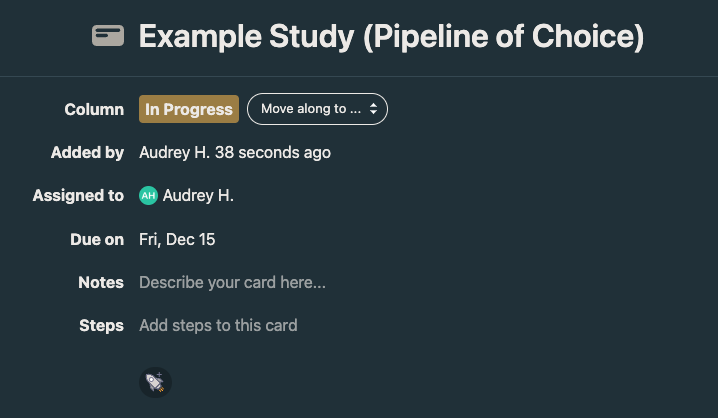
Add steps to your card, including everything you intend to do within this list as it applies to your codebase and study.
-
If you add more datasets to the s3, please make sure to update the tracking sheet.
For questions, suggestions, or to note any errors, post an issue on our Github.